hussein.chedi
Portrait of Hussein ChediHussein ChediOpen to new roles · Remote or Dallas, TX

~/hussein-chedi — AI/ML Solutions Architect

I build ML systemsthat train fasterand serve for less.

I'm Hussein Chedi — I design distributed training and LLM inference on GPU cloud, most recently for IBM's enterprise customers.

~/bench — llm-serving · 8× H100live

p95 latency

−0%

vs. baseline

GPU utilization

0%

from 58%

Training time

−0%

vs. baseline

GPU utilization by deviceavg 87%
before 58%
g0g1g2g3g4g5g6g7

$torchrun --nproc-per-node 8 train.py --strategy fsdp

nccl all-reduce · ring · 8 ranks ok

gpu util 58% → 87% ✓ healthy

Shipped at

  • IBM
  • Devsu
  • Intellectsoft

0+

Years of experience

0

Enterprise workloads

$0K

GPU spend saved / yr

About Me

I design the systems between a model and the business — training pipelines, low-latency inference and the platforms that run them.

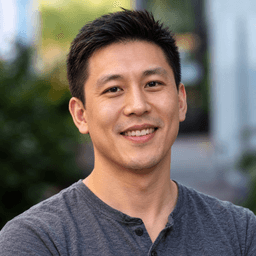
Portrait of Hussein Chedi

Since 2016

0

years building ML systems & backend software

Dallas, TX

Remote across US & LATAM time zones

B.Sc. Computer Science

The University of Texas at Dallas, Richardson, TX | Aug 2015 - May 2019

Career path

  1. 2016

    Software Engineer

    Intellectsoft

  2. 2020

    ML Engineer

    Devsu

  3. 2022

    Solutions Architect

    IBM

Selected Projects

04

live products

AI/ML & full-stack engineering

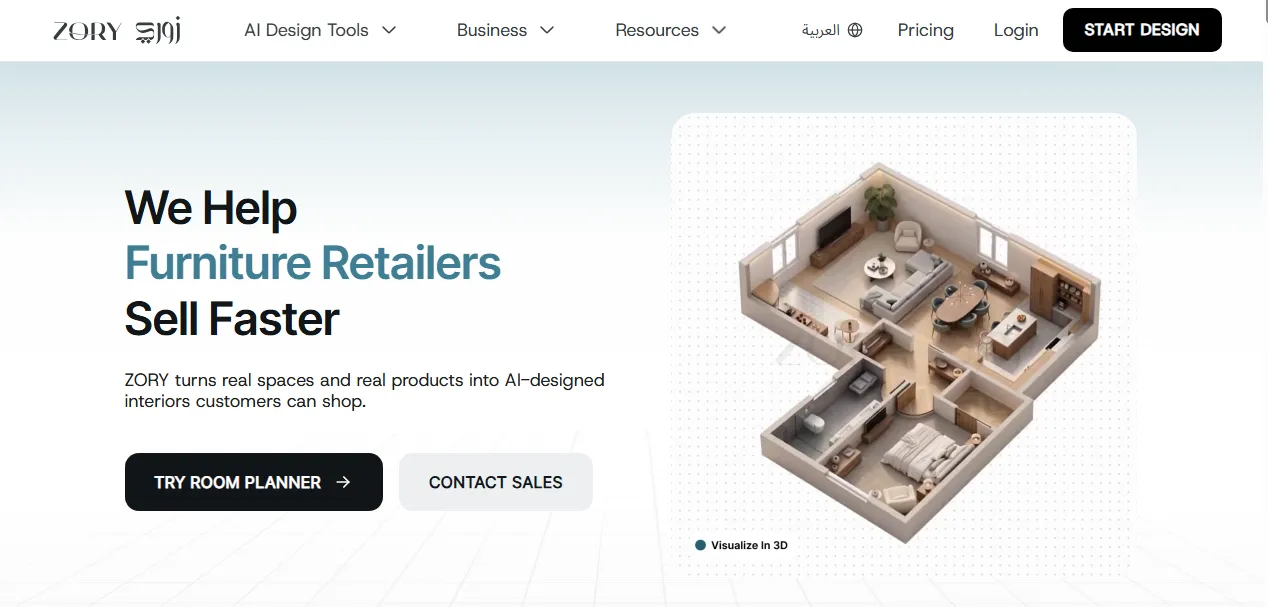
01 / 04Retail · Generative AI

Zory AI

AI-designed interiors that customers can shop.

My part

I built the ML pipeline behind the room designer: models fine-tuned in PyTorch and Hugging Face read a prompt, photo or sketch, then match every piece to the retailer's real SKU catalog. I served them as GPU inference on Kubernetes, so a styled, shoppable room comes back while the customer is still browsing.

  • Text & sketch to room
  • AI furniture finder
  • Room redesign
  • Retail SKU catalog
zory.ai/en
Zory homepage — We help furniture retailers sell faster
Open site

01/03Zory homepage — We help furniture retailers sell faster

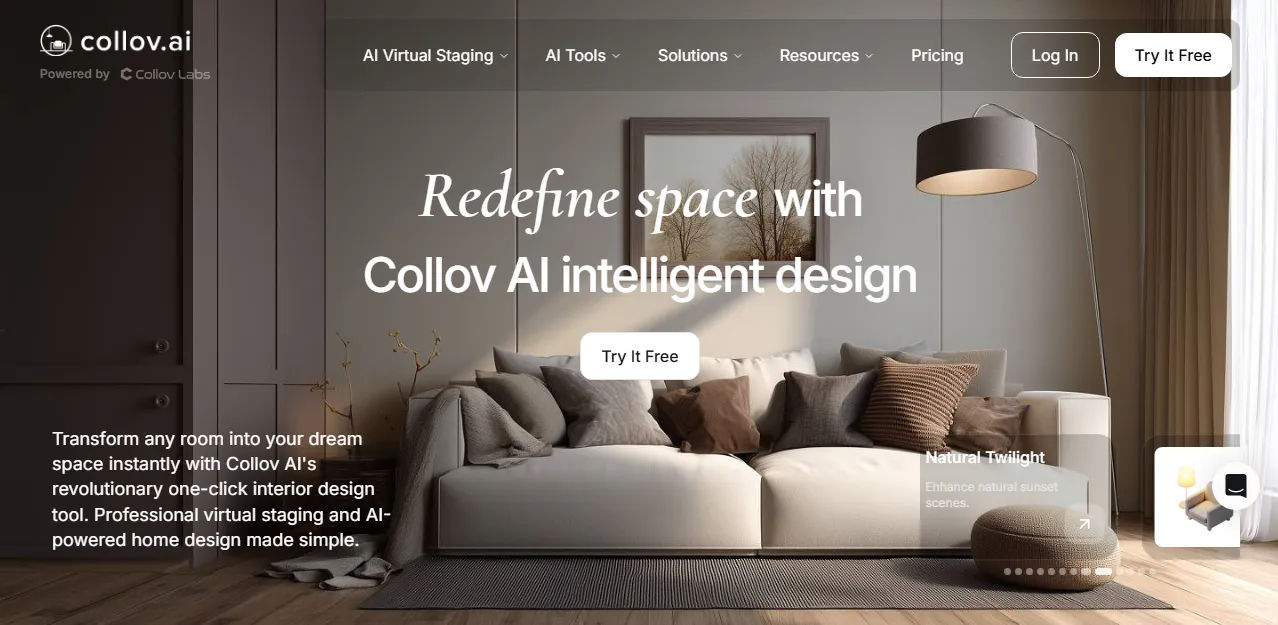
02 / 04PropTech · Generative AI

Collov AI

One-click AI virtual staging and interior design.

My part

I worked on the generative imaging engine behind staging and declutter — training image models in PyTorch on CUDA GPUs, then packaging them as containerized inference services. The same services power the one-click web app and the developer API, and scale on Kubernetes as listing volume grows.

  • Virtual staging
  • Generative image editing
  • Room declutter
  • Developer API
collov.ai
Collov AI homepage — Redefine space with Collov AI intelligent design
Open site

01/03Collov AI homepage — Redefine space with Collov AI intelligent design

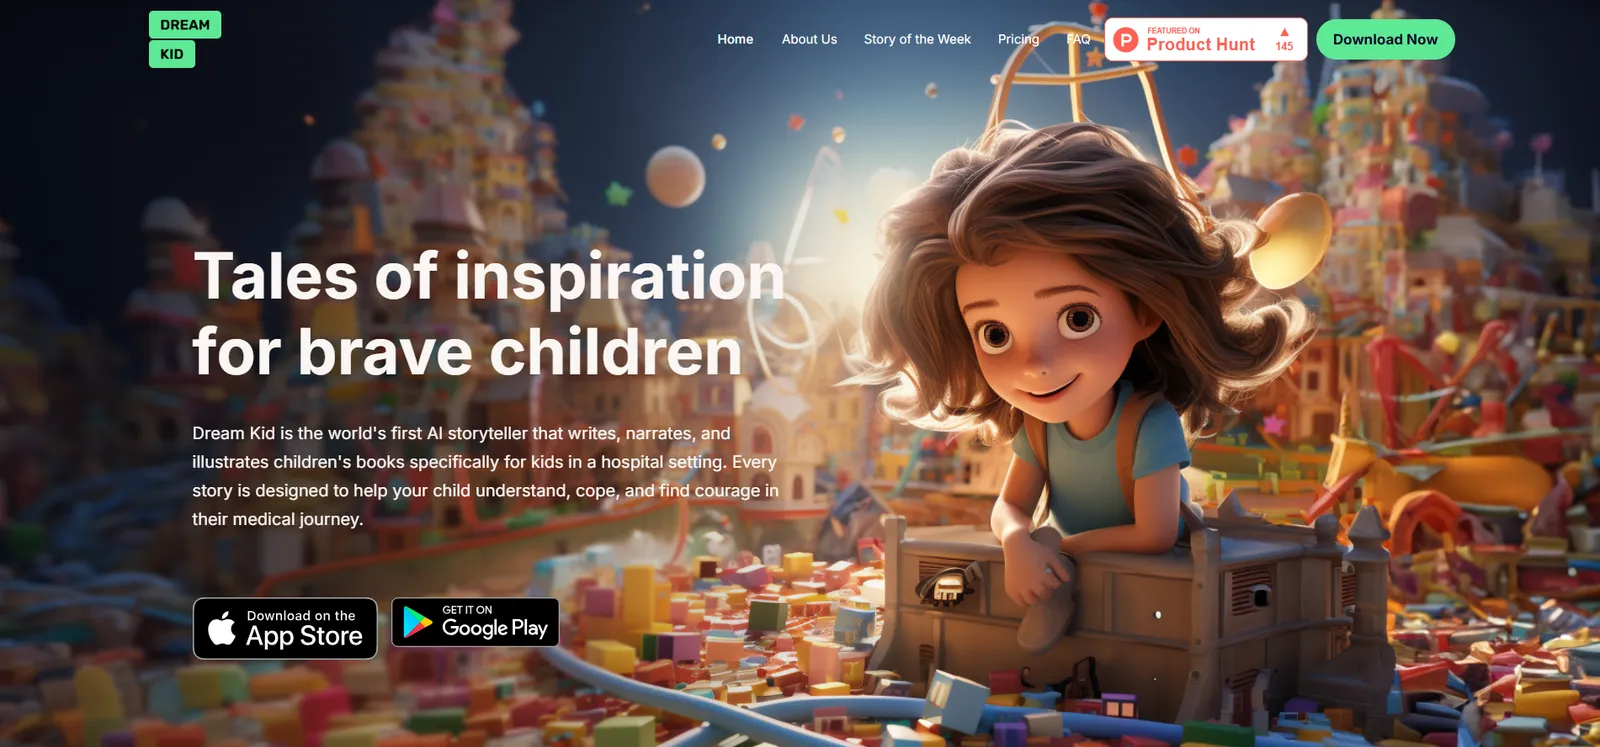
03 / 04Consumer AI · Mobile

DreamKid

AI stories where your child is the hero.

My part

I designed the story pipeline: an LLM writes each personalized chapter, then narration and illustration models turn it into a book a child can read and hear. I served the LLM with vLLM to keep stories quick to generate, and built the Python backend the iOS and Android apps call.

  • LLM story generation
  • AI narration
  • AI illustration
  • iOS & Android
dreamkid.ai
DreamKid homepage — Tales of inspiration for brave children
Open site

01/03DreamKid homepage — Tales of inspiration for brave children

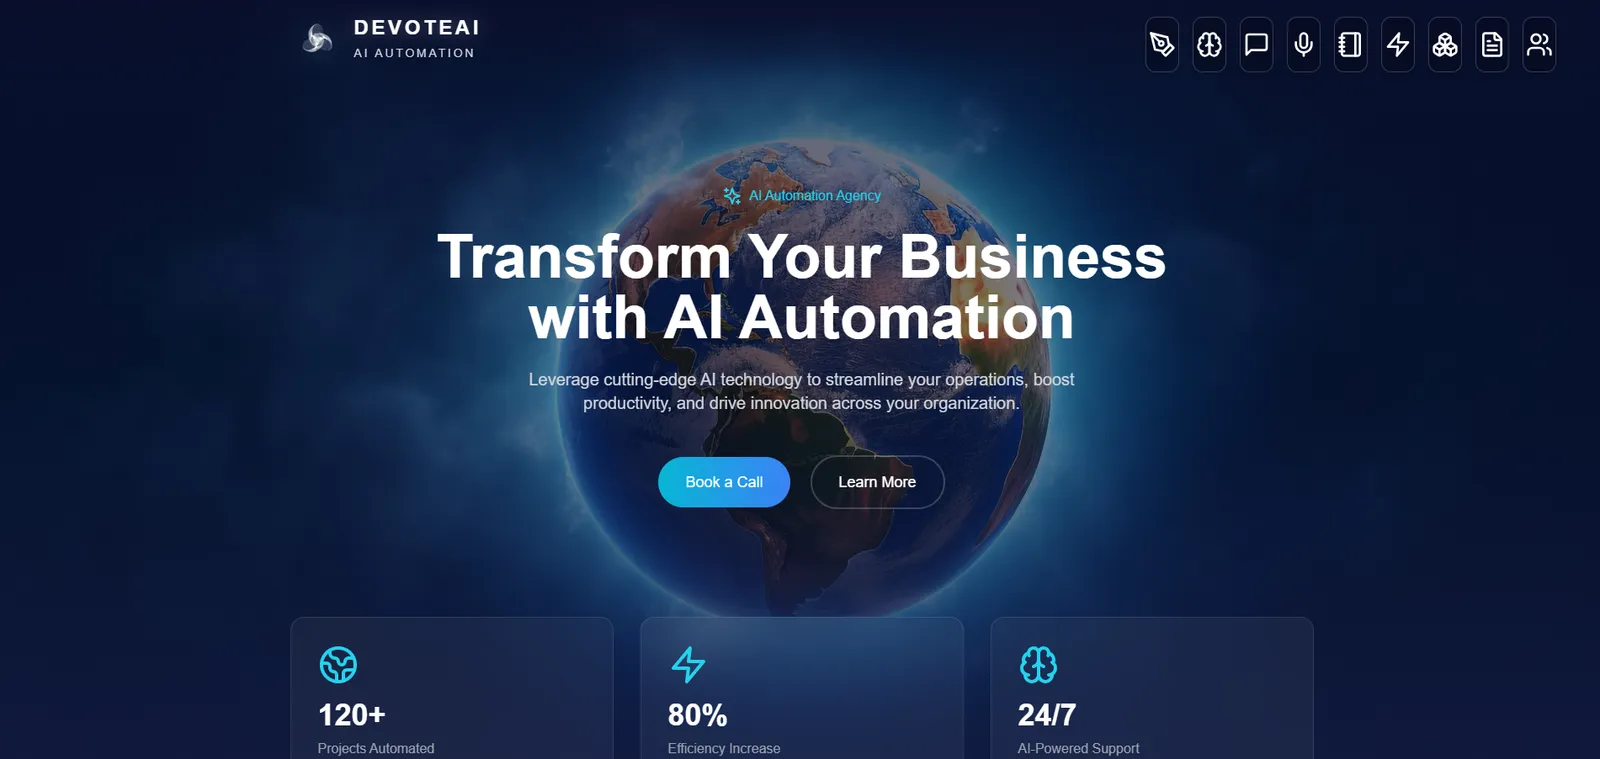
04 / 04AI automation

DevoteAI

AI automation that changes how a business runs.

My part

I architected the platform the agents run on — LLM serving with vLLM on Kubernetes, connected to each client's tools and workflows. MLOps pipelines in MLflow and GitHub Actions let every new chat or voice assistant be tested and shipped safely, then run around the clock.

  • AI agents
  • Chat & voice assistants
  • Workflow automation
  • 24/7 AI support
devoteai.co
DevoteAI homepage — Transform your business with AI automation
Open site

01/01DevoteAI homepage — Transform your business with AI automation

Experience

Each role a step closer to the hardware and the customer.

AI/ML Solutions Architect @ IBM

Sep 2022 — Aug 2026 Dallas, TX · Remote

Designed GPU training and inference platforms for enterprise customers on hybrid cloud.

  • −35%

    training time

  • −42%

    p95 latency

  • $180K

    yearly GPU savings

  • 87%

    GPU utilization

Stack

  • PyTorch FSDP
  • Kubernetes
  • vLLM
  • Triton
  • NCCL
  • CUDA
  • Terraform
  • Helm
  • Slurm
  • Hugging Face
Toolbox

From CUDA up to Kubernetes — chosen for what it does in production.

29 tools, one orbit.

  • drag to spin
  • hover a tool
  • pick an area
Contact

Hiring for ML platform or inference work — or want a second look at a GPU bill? My inbox is open.

Email me directly

I can help with

  • Distributed training
  • LLM inference
  • MLOps platforms
  • GPU cost reviews
  • Workshops & enablement
Open to new roles · Remote or Dallas, TX
What's this about?

Opens in your email app

201620202022Next